How I Talked a GPU Owner Out of Building a Token Factory Over Dinner
GPUs plus open-source parts do not make a token factory. Each layer hides 10–30× efficiency gaps. Tokens are commodities; TSMC-style neutrality wins.
13 min read
Inference infra, token economics & compute
GPUs plus open-source parts do not make a token factory. Each layer hides 10–30× efficiency gaps. Tokens are commodities; TSMC-style neutrality wins.
Our three weeks' tuning hit next-day P&L. Token economics cuts tech-to-profit: Zhipu 8x in 6mo; OpenAI Codex 5M/wk (GPT-5.5); MiniMax beat Baidu, fell.
Token cost is often judged by TTFT, TPOT, and throughput, but a 10x bill swing comes from KV cache hits, not speed. Model, server, and user layers must align.
GPT-5.5/Opus 4.7 demand is near-infinite, mid-tier models vanish, low-end compute idles; tokens resemble electricity but act like a mismatched gas station.
Gemini 3.5 Flash and Zhipu GLM-5.1's 400 token/s mode show that crossing ~5× inference speed unlocks a different product category, not just faster answers.
700+ AI Infra experiments cost me 35 hours on startup. I blamed GPT-5.5 fast mode, but GPUs waited on CPUs; Intel moves CPU:GPU from 1:8 to 1:1.
AIMA's management and after-sales layers are done, but the inference engine is missing: Ollama, llama.cpp, and vLLM all fall short, so I'm building one.
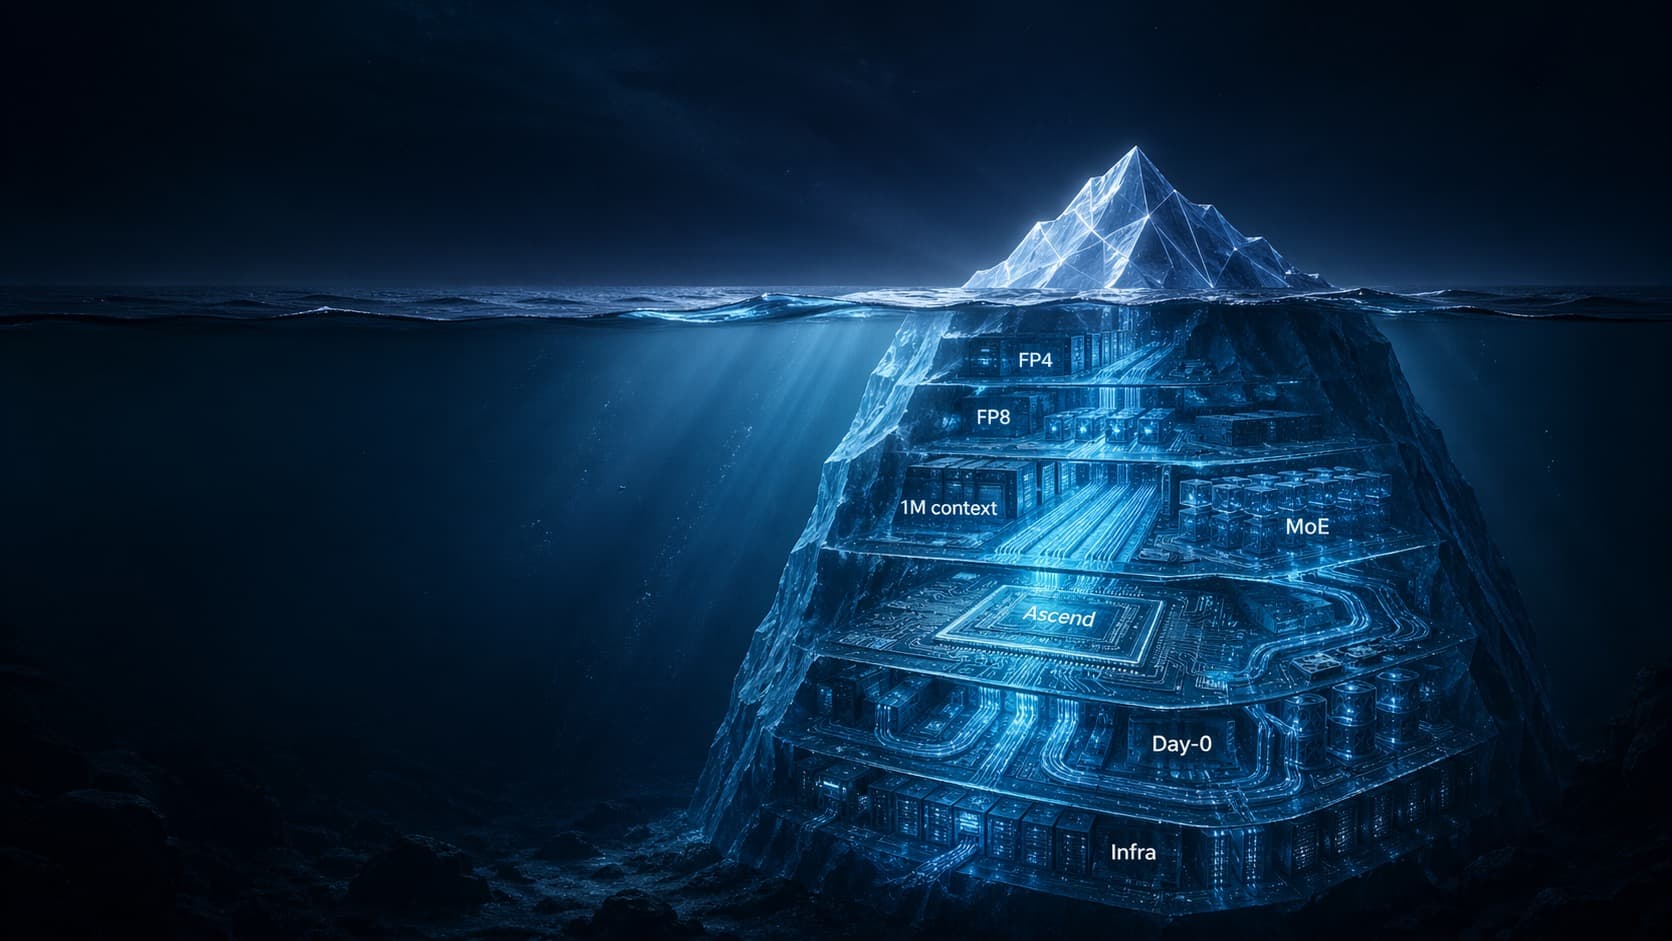
DeepSeek V4 matches Opus 4.6, but FP4, 1M-token context, and day-0 chip support stress inference infra. GPT-5.5, Vision Banana, and LPM 1.0 landed too.
LLM pricing is stuck: chip controls cap supply, while three user groups pull demand into different shapes. The once-obvious Coding Plan is now under fire.
Claude Opus 4.6 built a plugin in 30 min after two days with one model. An AI agent unlocked my PC in 30 min. I built Aima Service for AI help on any device.
Skip remote help. Paste one command, enter the invite code, AI installs OpenClaw, connects an LLM, and integrates Feishu while you answer a few questions.
We open-sourced AIMA, a Go binary with 57 MCP tools and a YAML knowledge base for heterogeneous AI inference, as AI servers halve in value in three months.
Get notified when I publish new posts. No spam, ever.
Only used for blog update notifications. Unsubscribe anytime.